whisper.cpp
NEON & MPS 🆚 CoreML
下载模型(large-v3)
models/download-ggml-model.sh large-v3
NEON & MPS
编译
make clean
make -j
main 帮助 ./main --help usage: ./main [options] file0.wav file1.wav ...
NEON & MPS 🆚 CoreML
下载模型(large-v3)
models/download-ggml-model.sh large-v3
NEON & MPS
编译
make clean
make -j
main 帮助 ./main --help usage: ./main [options] file0.wav file1.wav ...
快速开始
克隆代码
git clone https://github.com/QwenLM/Qwen.git
cd Qwen
创建虚拟环境
python -m venv env
source env/bin/activate
安装依赖
pip install -r requirements.txt
创建大模型链接
mkdir Qwen
ln -s /Users/junjian/HuggingFace/Qwen/Qwen-14B-Chat Qwen/Qwen-14B-Chat
ln -s /Users/junjian/HuggingFace/Qwen/Qwen-1_8B Qwen/Qwen-1_8B
ln -s /Users/junjian/HuggingFace/Qwen/Qwen-1_8B-Chat Qwen/Qwen-1_8B-Chat
ln -s /Users/junjian/HuggingFace/Qwen/Qwen-7B-Chat Qwen/Qwen-7B-Chat
聊天
python cli_demo.py
python web_demo.py
FastChat
克隆代码
git clone https://github.com/lm-sys/FastChat
cd FastChat
创建虚拟环境 python -m venv env source env
克隆代码
git clone https://github.com/ml-explore/mlx-examples
cd mlx-examples
创建虚拟环境
python -m venv env
source env/bin/activate

pip install -r llms/phi2/requirements.txt
pip install -r llms/qwen/requirements.txt
创建大模型链接 mkdir llms/phi2/microsoft ln -s /Users/junjian/HuggingFace/microsoft/phi-2 llms/phi2/microsoft/phi-2 mkdir llms/qwen/Qwen ln -s /Users/junjian/HuggingFace/Qwen/Qwen-14B-Chat llms/qwen/Qwen/Qwen-14B-Chat ln -s /Users/junjian/HuggingFace/Qwen/Qwen-1_8B llms/qwen/Qwen/Qwen-1_8B ln -s /Users/junjian/HuggingFace/Qwen/Qwen-1_8B-Chat llms/qwen/Qwen/Qwen-1_8
统一内存:与 MLX 和其他框架的显着区别是统一内存模型。 MLX 中的数组位于共享内存中。 MLX 阵列上的操作可以在任何支持的设备类型上执行,而无需传输数据。
创建虚拟环境
mkdir ml-explore && cd ml-explore
git clone https://github.com/ml-explore/mlx
git clone https://github.com/ml-explore/mlx-examples

python -m venv env
source env/bin/activate
cd llms/phi2
pip install -r requirements.txt
使用已经下载的模型
mkdir microsoft
ln -s /Users/junjian/HuggingFace/microsoft/phi-2 microsoft/phi-2
转换模型
python convert.py
这将生成 MLX 可以读取的 weights.npz 文件。
-rw-r--r-- 1 junjian staff 5.2G 12 20 20:36 weights.npz
Phi-2: The surprising power of small language models
创建虚拟环境
conda create -n huggingface python==3.10.9
conda activate huggingface
安装依赖包
conda install pytorch torchvision -c pytorch
pip install transformers
pip install einops
下载模型
huggingface-cli download microsoft/phi-2 --local-dir microsoft/phi-2 --local-dir-use-symlinks False
代码 import torch from transformers import AutoModelForCausalLM, AutoTokenizer torch.set_default_device("mps") model = AutoModelForCausalLM.
下载代码
git clone https://github.com/Stability-AI/generative-models.git Stability-AI/generative-models
cd Stability-AI/generative-models/
创建虚拟环境
python -m venv env
source env/bin/activate
pip install -r requirements/pt2.txt
pip install .
Apple Silicon 上没有安装成功,安装包 triton 不支持
下载模型
pip install "huggingface_hub[cli]"
huggingface-cli download stabilityai/sdxl-turbo --local-dir checkpoints --local-dir-use-symlinks False
CLIP huggingface-cli download openai/clip-vit-large-patch14 --lo
TGI 是一个用于部署和服务大型语言模型(LLM)的工具包。 TGI 为最流行的开源 LLM 提供高性能文本生成,包括 Llama、Falcon、StarCoder、BLOOM、GPT-NeoX 和 T5 。
系统架构
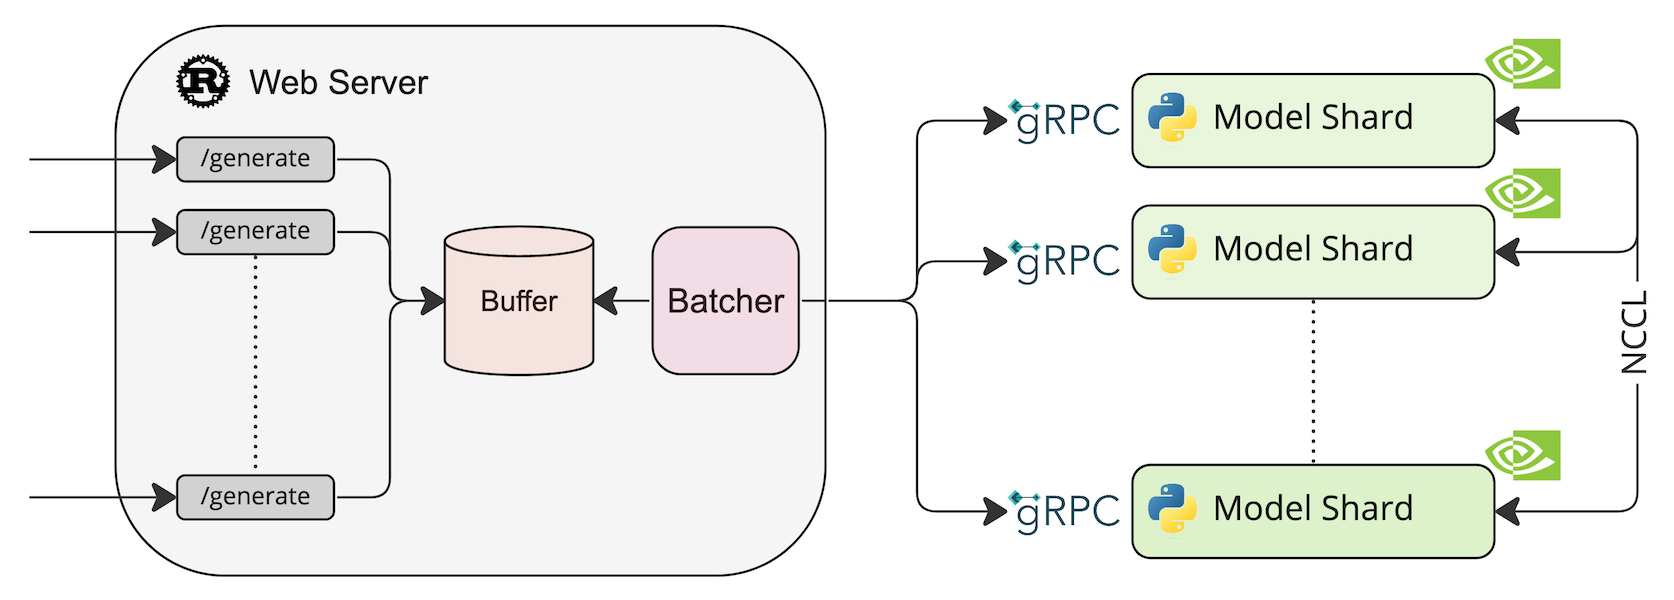
部署模型 HuggingFaceH4/zephyr-7b-beta model=HuggingFaceH4/zephyr-7b-beta volume=$PWD/data # Avoid downloading weights every run docker run --
部署
ollama run llama2
通过 API 访问
curl http://localhost:11434/api/generate -d '{
  "model": "llama2",
  "prompt": "Why is the sky blue?",
  "stream": false
}'
ollama 帮助 ollama --help Large language model runner Usage: ollama [flags] ollama [command] Available Commands: serve Start ollama create Create a model from a Modelfile show Show information for a model run Run a model pull Pull a model from a registry push Push a model to a registry list List models cp Copy a model rm Remove a model help Help about any comman
在 macOS 安装 GitHub CLI
brew install gh
brew upgrade gh
gh auth login
? What account do you want to log into? GitHub.com
? What is your preferred protocol for Git operations on this host? HTTPS
? Authenticate Git with your GitHub credentials? Yes
? How would you like to authenticate GitHub CLI? Login with a web browser

! First copy your one-time code: EA2E-F864
Press Enter to open github.com in your browser...
✓ Authentication complete.
gh auth status
github.com
  ✓ Logged in to github.com account wang-junjian (keyring)
  - Active account: true
  - Git operations protocol: https
  - Token: gho_************************************
  - Token scopes: 'gist', 'read:org', 'repo', 'workflow'
llama.cpp
构建
❶ 克隆 [llama.cpp][llama.cpp] 仓库
git clone https://github.com/ggerganov/llama.cpp.git
cd llama.cpp
❷ make
make -j
❸ 安装依赖
pip install -r requirements.txt
获得 Facebook LLaMA2 模型
可以从 TheBloke 下载已转换和量化的模型。
下载 GGUF 模型
huggingface-cli pip install huggingface_hub REPO_ID=TheBloke/Llama-2-7B-chat-GGUF FILENAME=llama-2-7b-chat.Q4_K_M.
[TensorRT-LLM][TensorRT-LLM]
TensorRT-LLM 为用户提供了易于使用的 Python API 来定义大型语言模型 (LLM) 并构建包含最先进优化的 TensorRT 引擎,以便在 NVIDIA GPU 上高效地执行推理。 TensorRT-LLM 还包含用于创建执行这些 TensorRT 引擎的 Python 和 C++ 运行时的组件。
# TensorRT-LLM uses git-lfs, which needs to be installed in advance.
apt-get update && apt-get -y install git git-lfs

git clone https://github.com/NVIDIA/TensorRT-LLM.git
cd TensorRT-LLM
git submodule update --init --recursive
git lfs install
git lfs pull

make -C docker release_build
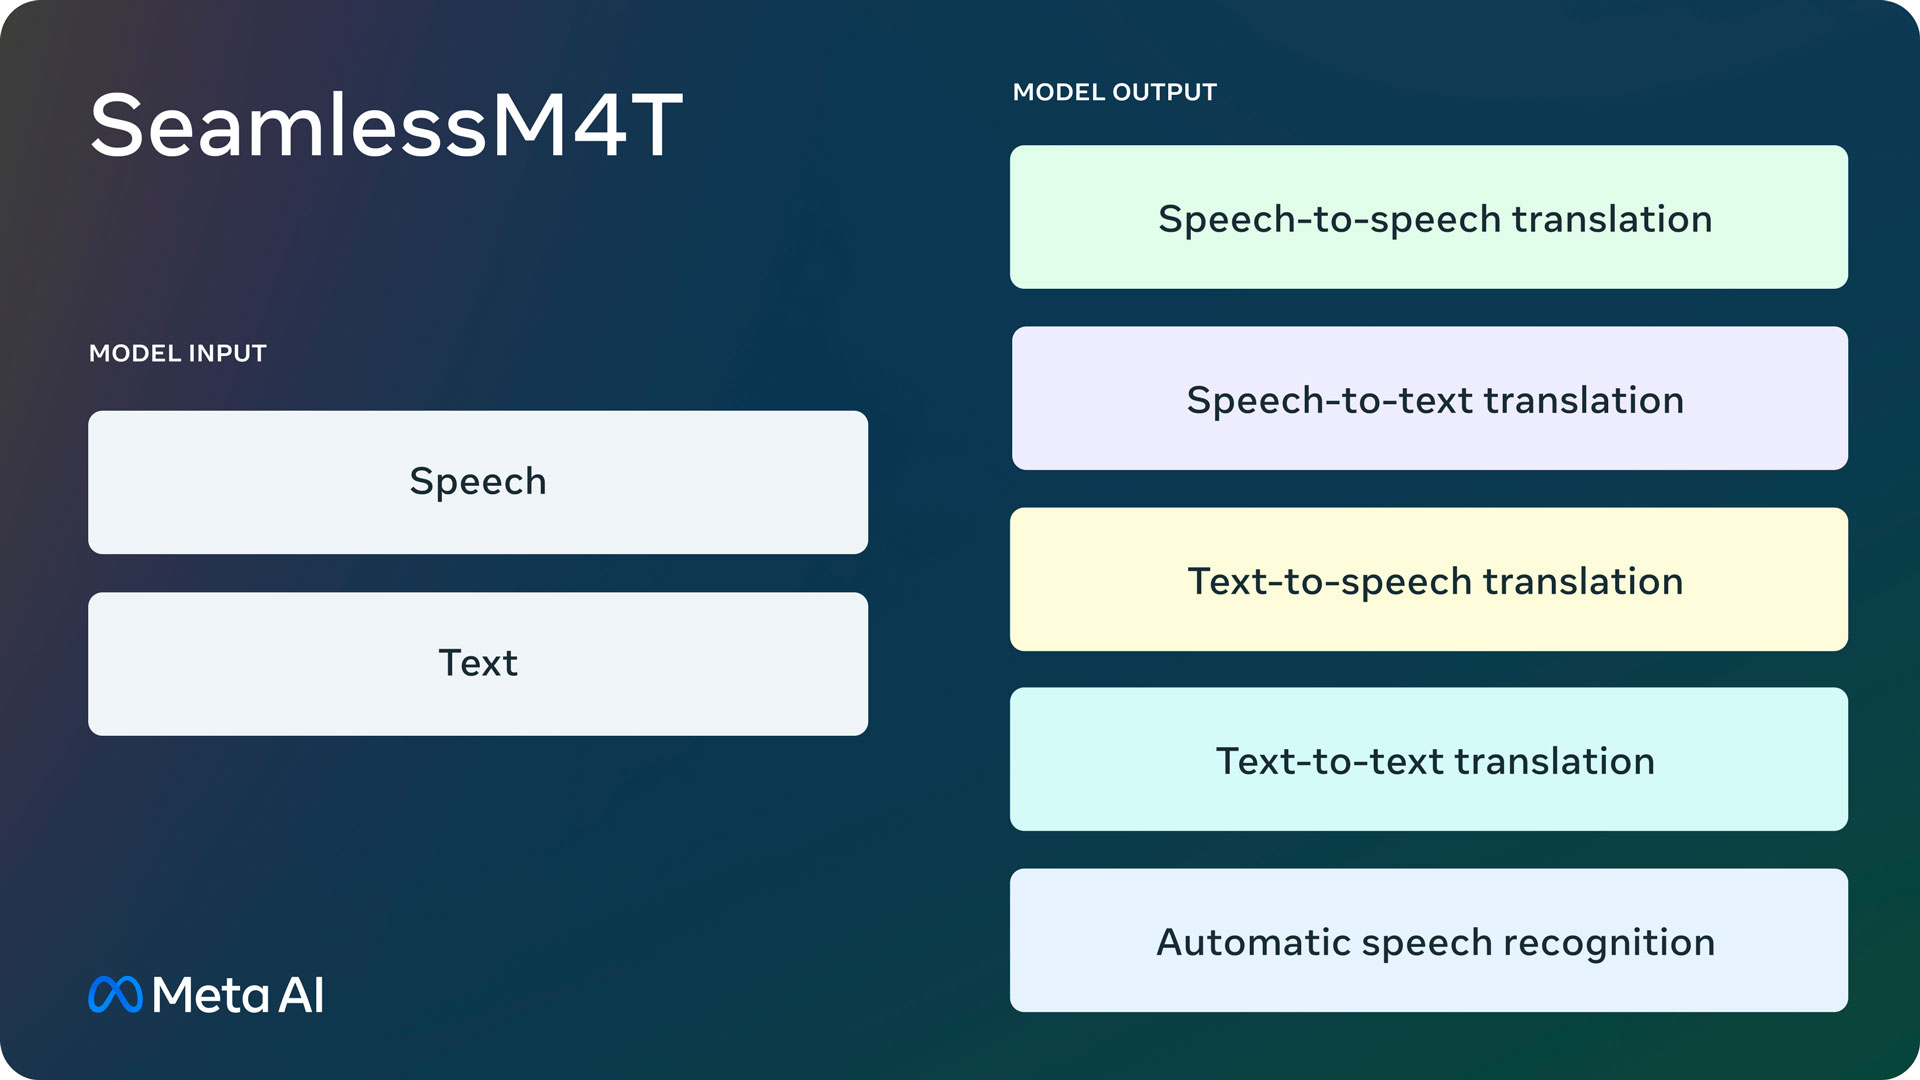
SeamlessM4T 概述
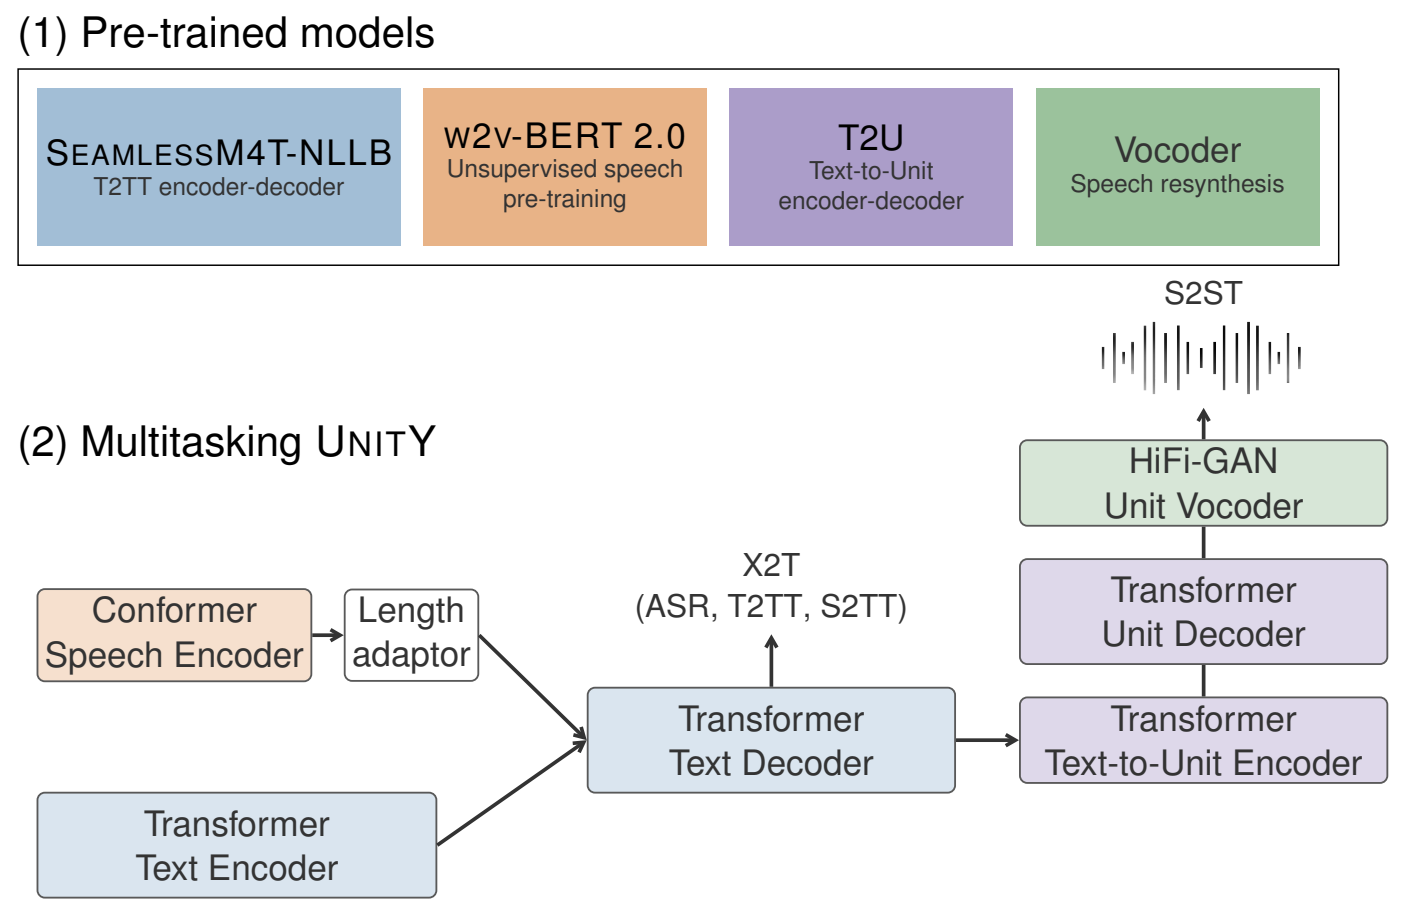
安装 [Seamless Communication][seamless_communication]
克隆仓库 git clone https://github.
文档
这里使用的文档是:合作方人员出勤及结算管理信息化支撑规则
一、出勤打卡
出勤打卡包括:正常出勤打卡、出差打卡、外出打卡、加班打卡。

1. 正常出勤打卡:指正常的出勤办公打卡。
(1)全天出勤打卡:上班打卡:8点30分之前打卡。下班打卡:17点30分之后打卡。
(2)半天出勤打卡。上午打卡时间段:8点30分之前、12点之后。下午时间段:13点之前,17点30分之后。
(3)打卡(考勤机或企业微信打卡)形式按部门要求为准,最小半天为统计单位。

2. 出差打卡:指出差地出勤办公或在途期间打卡。
(1)固定出差地打卡:打卡时间参照第1条正常出勤上下班打卡;无法定位有效范围的找部门管理员修改工作打卡位置。(具体按照各部门要求执行)
(2)出差在途打卡(使用手机外出打卡)。到车站坐车前打外出打卡一次,到达目的地后打外出打卡一次(往返同理)。下午出差的,上午需打正常出勤卡(上午正常出勤须闭环打卡);上午到达出差地的,下午需打一次外出打卡或上下班打卡。

3. 外出打卡:指外出办事打卡。提外出申请后,可以打外出卡,打外出卡时间需在申请时间内:
(1)半天外出:如外出时间在上午(12点前) 或者下午(12点后),则另外半天需正常出勤打卡。
(2)跨12点外出:如外出跨度期间包含12点,则12点前、12点后分别打外出卡即可记为合格出勤。
// ...
提示词模板 """ {
下载 GPT4All 客户端(macOS)
下载模型

聊天

基于目录构建本地文档集合
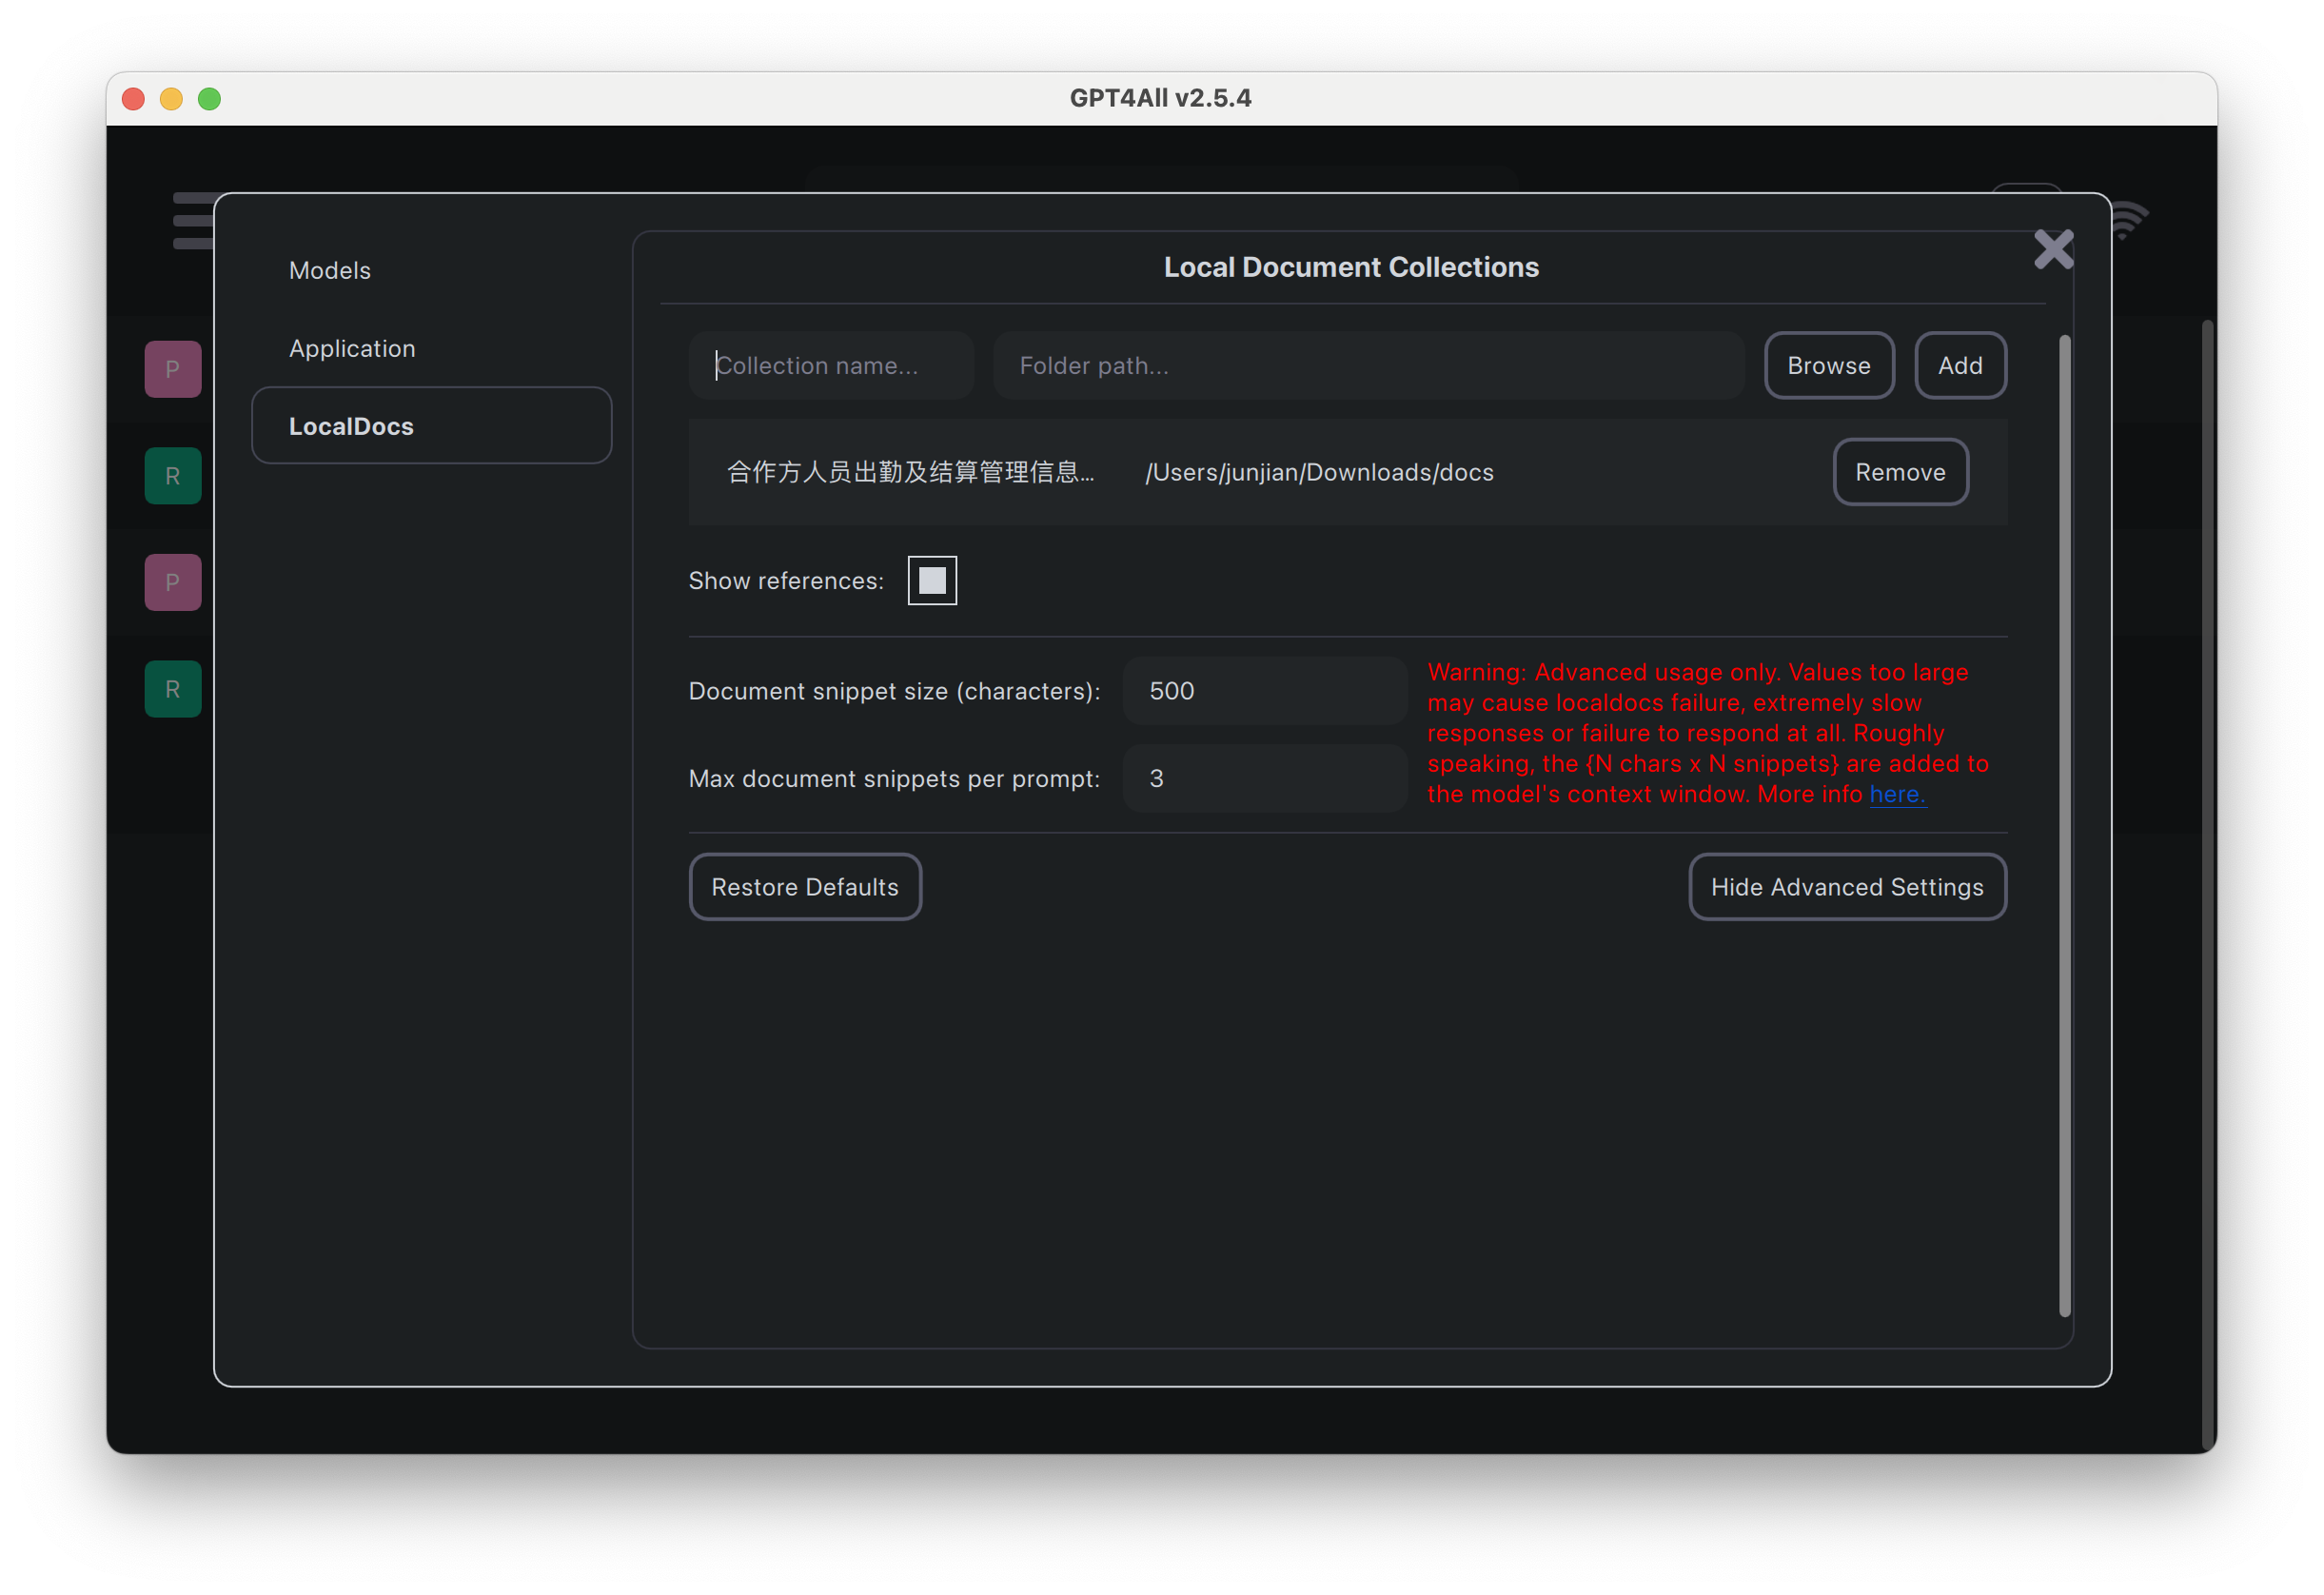
本地服务

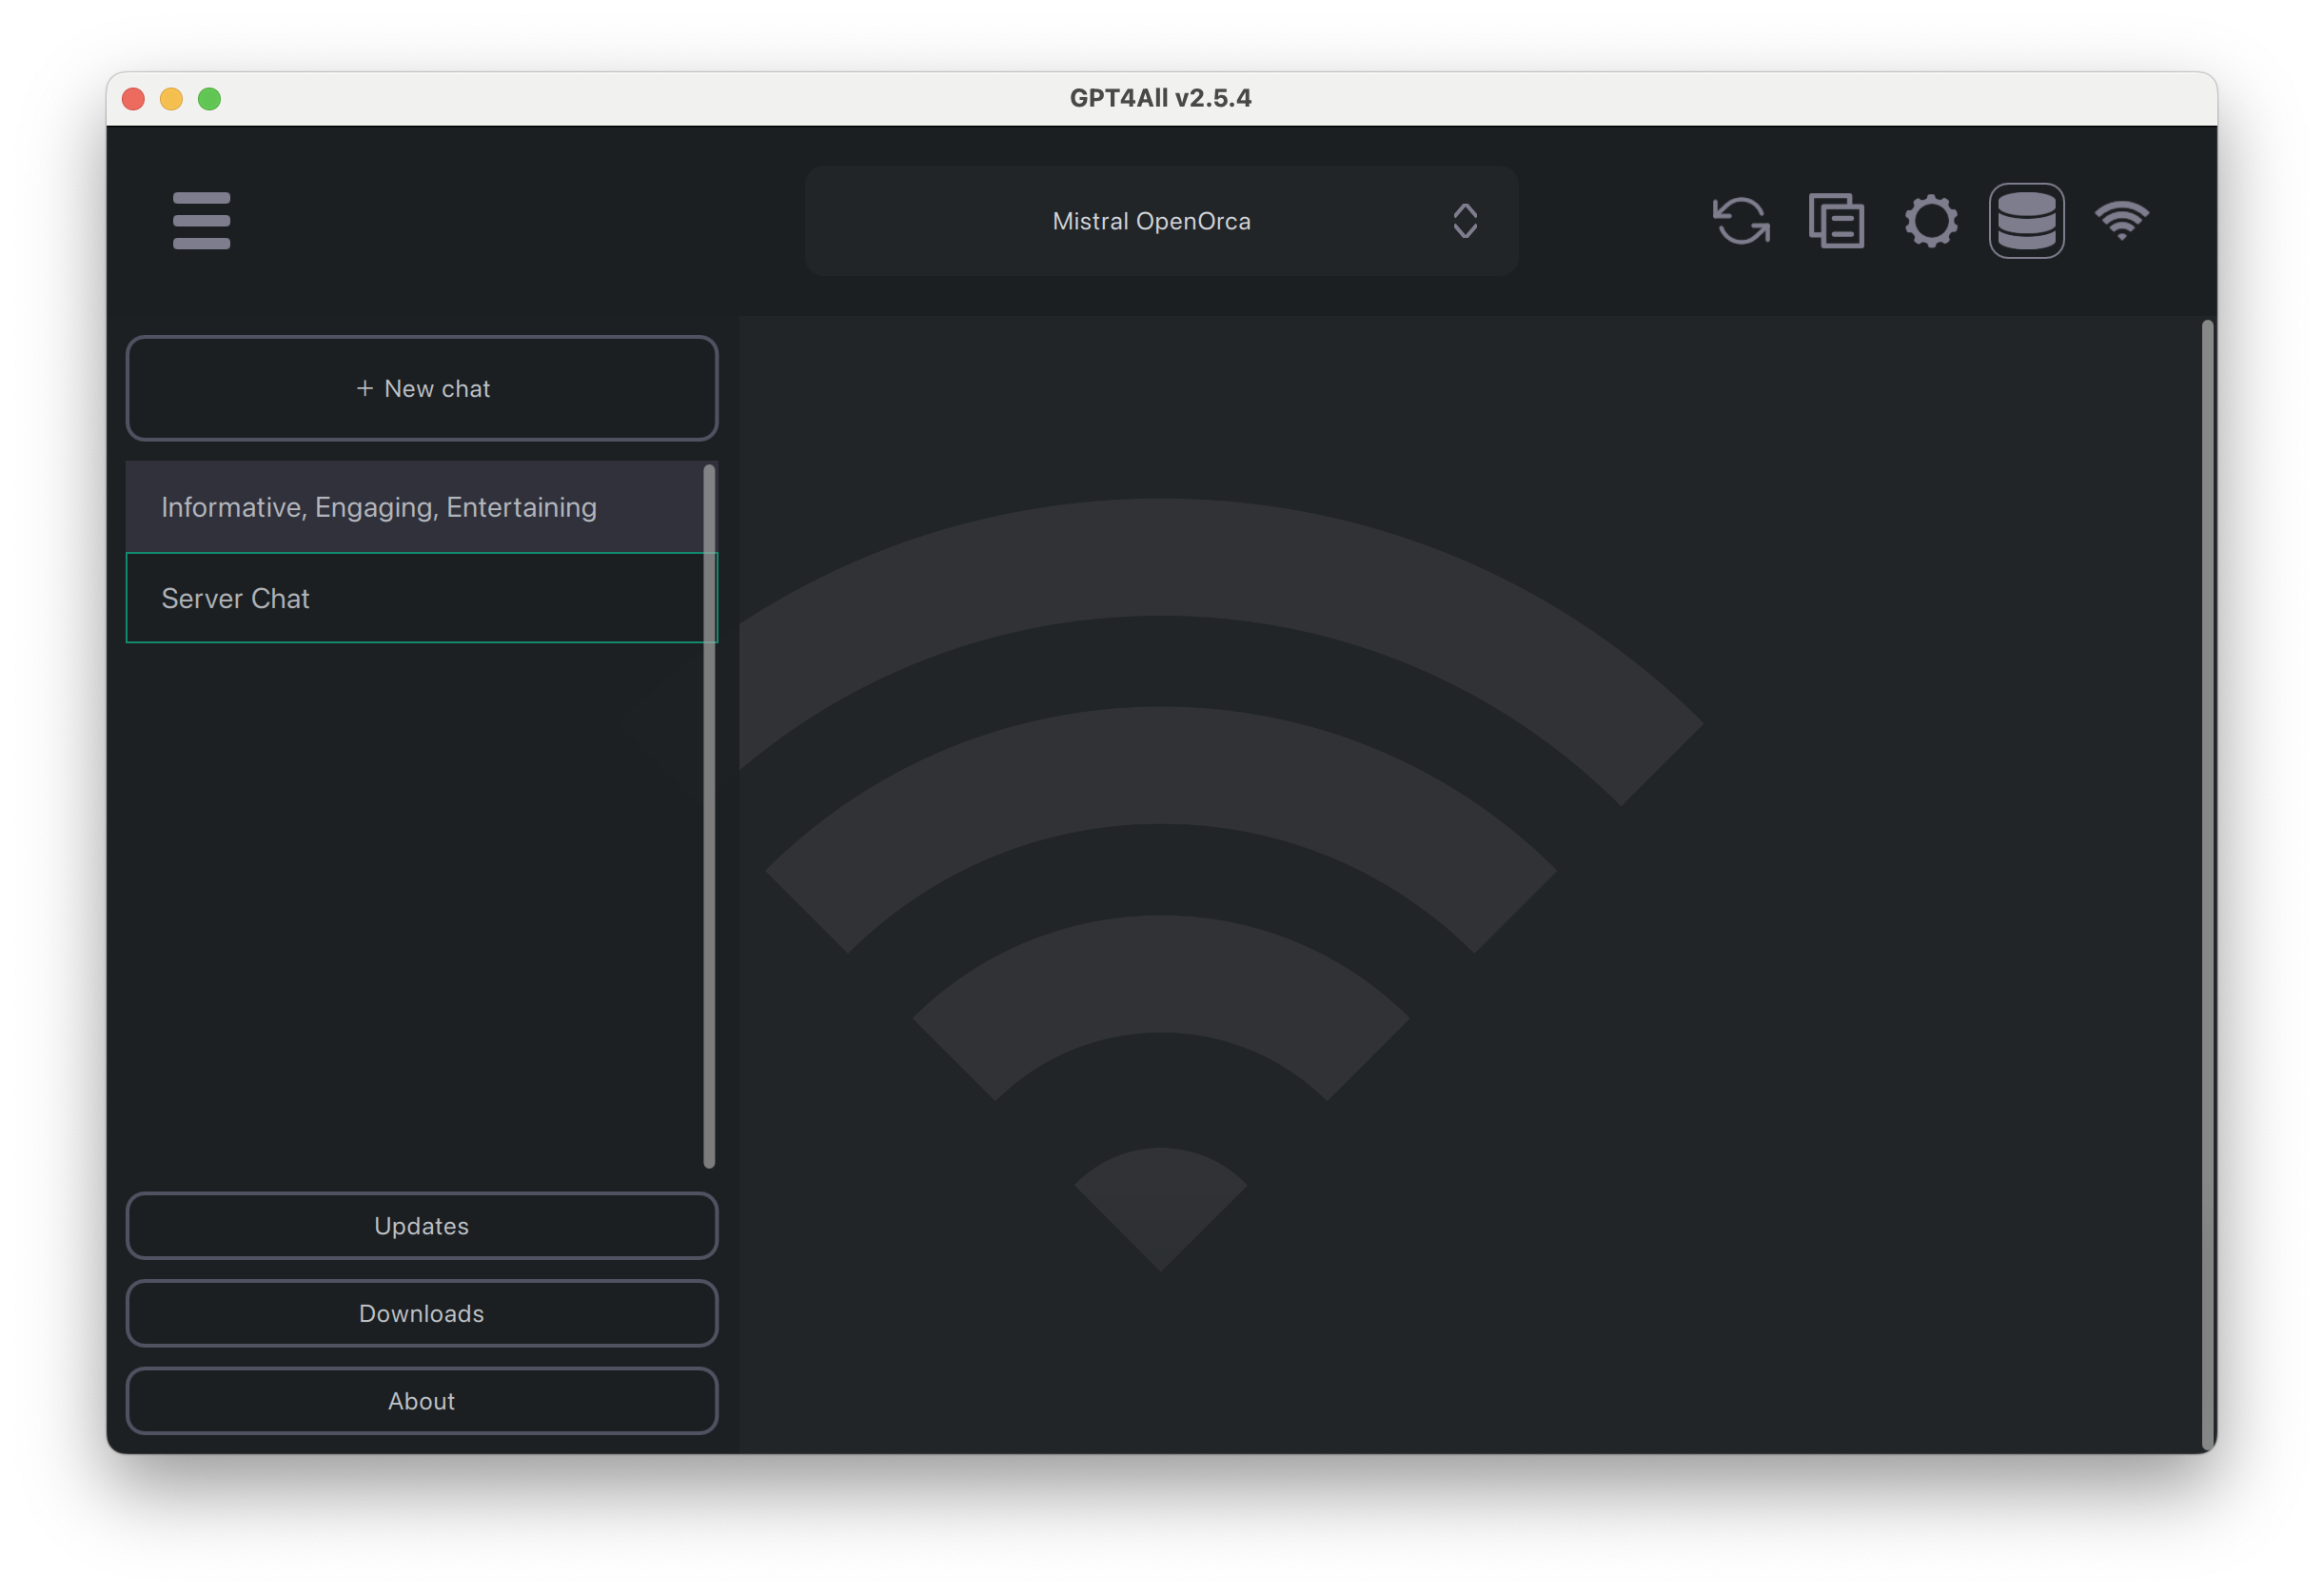
查看本地下载的模型 ll /Users/junjian/Library/Application\ Support/nomic.ai/GPT4All/*.gguf -rw-r--r--@ 1 junjian staff 44M 12 3 10:30 /Users/junjian/Library/Application Support/nomic.ai/GPT4All/all-MiniLM-L6-v2-f16.gguf -rw-r--r--@ 1 junjian staff 1.3G 12 3 12:53 /Users/junjian/Library/Application Support/nomic.ai/GPT4All/incomplete-nous-hermes-llama2-13b.Q4_0.gguf -rw-r--r--@ 1 junjian staff 3.8G 12 3 10:09 /Users/junjian/Library/Application Support/nomic.ai/GPT4All/mistral-7b-openorca.Q4_0.gguf -rw-r--r--@ 1 junjian staff 3.
安装
brew update
brew install nginx
启动服务
brew services start nginx
Docroot is: /opt/homebrew/var/www

The default port has been set in /opt/homebrew/etc/nginx/nginx.conf to 8080 so that
nginx can run without sudo.

nginx will load all files in /opt/homebrew/etc/nginx/servers/.

To start nginx now and restart at login:
  brew services start nginx
Or, if you don't want/need a background service you can just run:
  /opt/homebrew/opt/nginx/bin/nginx -g daemon\ off\;
/opt/homebrew/etc/nginx/nginx.conf 修改端口号/opt/homebrew/var/www/index.html 修改默认页面停止服务
brew services stop nginx
重启服务 brew services restar
该文档详细介绍了 2023年全国行业职业技能竞赛,涵盖了多个技术任务。任务一侧重于语音处理,通过Python代码展示了如何利用腾讯云API进行语音识别和语音合成,包括音频文件的Base64编码转换和请求参数配置,并输出了实际的识别结果。任务二则聚焦于语音模型,阐述了声学模型的初始化、加载预训练模型以及语音识别的整个流程,并提到了模型训练的配置。任务三涉及文本处理,通过requests库抓取网页内容,并利用re、BeautifulSoup和lxml.etree等工具进行网页内容解析和文本提取,同时展示了文本清洗、数据扩充以及使用Stanford CoreNLP进行中文分词、词性标注和命名实体识别。任务四是数据分析与可视化,展示了如何从Excel文件中读取急诊科就诊数据,并计算男女比例、每日就诊人数和各诊室就诊人数,最终通过matplotlib库生成饼状图、柱状图和折线图进行数据可视化。
2023年全国行业职业技能竞赛 第二届全国电子企业职业技能竞赛
任务一
任务1.1
任务1.2
通过 CPU 服务器访问 GPU 服务器
NGINX 配置文件
sudo vim /etc/nginx/sites-available/default
配置反向代理
server {
    listen 8888;
    server_name cpu1;

    location / {
        proxy_pass http://cpu1:8300/;
    }
}
配置 WebSocket 反向代理
server {
    listen 8001;
    server_name cpu1;

    location / {
        proxy_pass http://gpu1:8001;
        proxy_http_version 1.1;
        proxy_set_header Upgrade $http_upgrade;
        proxy_set_header Connection "upgrade";
    }
}
proxy_http_version 1.1,proxy_set_header Upgrade $http_upgrade和proxy_set_header Connection "upgrade"这些行是为了支持WebSocket连接。
配置多个反向代理 server { listen 8888; server_name cpu1; location /oneapi { proxy_pass http://cp
13 号 上午 GPU 服务器突然不能访问了,可以通过 CPU 服务器访问 GPU 服务器。这一周一直在查找问题,这里记录一下过程。
traceroute 路由追踪
traceroute gpu1
traceroute to gpu1 (172.16.33.66), 64 hops max, 52 byte packets
 1  * * *
 2  172.16.136.2 (172.16.136.2)  7.462 ms  3.820 ms  3.014 ms
 3  * * *
 4  * * *
 5  * * *
 6  * * *
 7  * * *
 8  * * *
 9  * * *
10  * * *
traceroute cpu1
traceroute to cpu1 (172.16.33.157), 64 hops max, 52 byte packets
 1  * * *
 2  172.16.136.2 (172.16.136.2)  7.827 ms  4.712 ms  3.162 ms
 3  * * *
 4  cpu1 (172.16.33.157)  8.619 ms  4.205 ms  4.982 ms
tcpdump 抓包
在GPU服务器上抓取 22 端口的数据包
使用 Transformers 的 Pipeline 进行推理
安装依赖包
pip install datasets evaluate transformers[sentencepiece]
英文情感分类
from transformers import pipeline

classifier = pipeline("sentiment-analysis")
classifier(
    [
        "I've been waiting for a HuggingFace course my whole life.",
        "I hate this so much!",
    ]
)
安装
pip
pip install "fschat[model_worker,webui]"
源代码
这种方式安装比较容易调试,适合开发者。
克隆代码
git clone https://github.com/lm-sys/FastChat.git
cd FastChat
创建环境
python -m venv env
source env/bin/activate
安装
没有找到匹配的文章